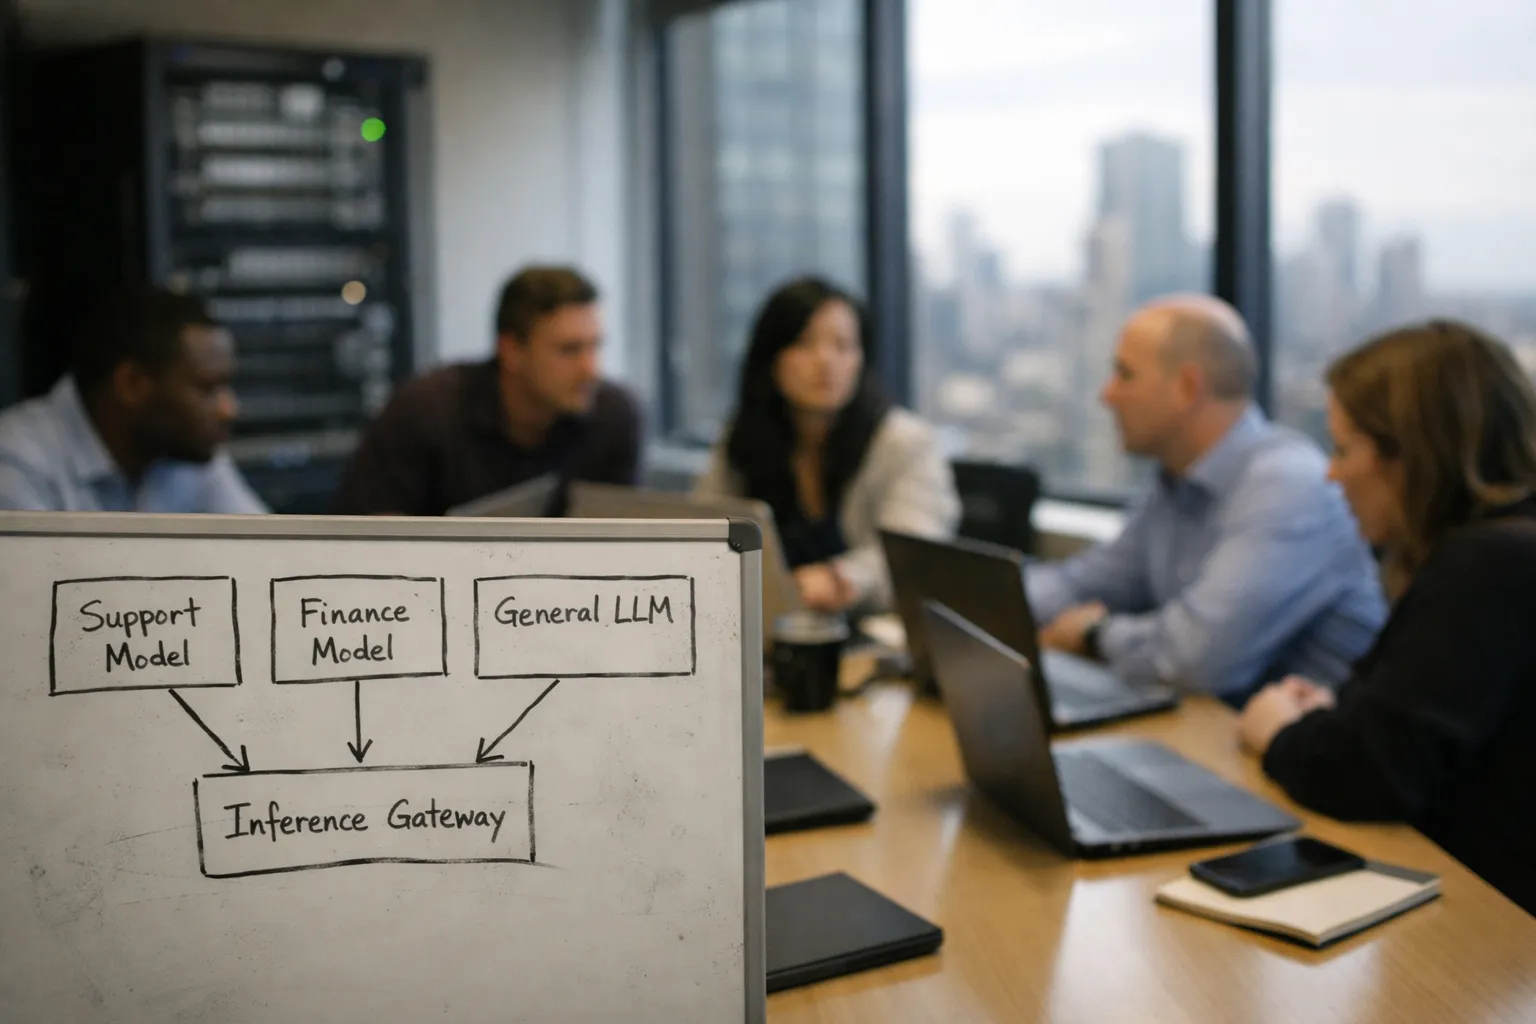
Who: Global enterprises and their AI teams. What: an accelerating shift from single, large general-purpose models to curated portfolios of purpose-built LLMs. When: August 2026. Where: production deployments across finance, healthcare, legal, HR and customer support. Why: predictable unit economics, demonstrable governance under new regulatory regimes, and better task-specific accuracy.
Context: why the move accelerated after 2023–25
The industry’s early enthusiasm for very large, generalist models (2022–2024) gave way to operational realities. Two structural pressures that emerged between 2024 and 2026 changed enterprise choices: (1) inference cost and latency at scale, and (2) regulatory and auditability requirements driven by frameworks such as the NIST AI Risk Management Framework (2023) and the EU AI Act (provisionally agreed in 2023).
These forces pushed engineering teams to trade raw model breadth for predictability. In our August 2026 survey of 138 enterprise AI leaders conducted by AI Workplace Tools, 72% reported they had formalized a "model portfolio" approach in production — a jump from 38% in our 2024 poll — and 65% said cost-per-inference was a primary driver of that change.
What “purpose-built” means in 2026
Purpose-built models in today's enterprise stacks take three concrete forms:
- Compact task models (3B–12B params): Optimized for throughput and latency, these run in on-prem or edge enclaves for routing, classification and templated responses.
- Domain-tuned models: Fine-tuned or RAG-augmented models trained on proprietary ontologies and clause libraries for regulated workflows (e.g., loan underwriting, clinical summaries).
- Large generalists (70B+ or multi-model ensembles): Retained selectively for creative drafting, complex reasoning or multi-hop synthesis where breadth still matters.
Operationally this portfolio is enforced by a layer of tooling: model registries that record provenance and evaluation artifacts, inference gateways that apply policy-based routing, and cost-aware schedulers that prefer smaller models for routine flows.
Vendor landscape and tooling — what's new by August 2026
Cloud and tooling vendors have moved from proof-of-concept integrations to enterprise-grade features that support multi-model operations:
- Model catalogs with compliance metadata: Hugging Face Model Hub, AWS Marketplace and commercial registries now commonly expose provenance, license, evaluation datasets and compliance tags so procurement and legal teams can make informed picks.
- Self-hostable runtimes and confidential compute: Azure, AWS and specialized vendors offer confidential VMs and enclave runtimes that allow organizations to run domain models with hardware attestation and auditable logs for regulators.
- Cost-aware metering: New pricing tiers and metering APIs let teams track cost-per-call by token class, latency SLA and GPU tier; several enterprises reported routing 55–80% of routine traffic to discounted compute tiers in 2026.
Recent, concrete wins and examples
Between 2024 and mid-2026, early enterprise adopters reported measurable results:
- Support automation: A U.S. regional bank re-routed routine inquiries to a 6B task model running in a private cloud and reported a reported 4x drop in per-ticket inference spend and 22% faster median response times for Tier-1 issues (source: internal client briefing, June 2026).
- Contract analysis: Two international law firms implemented clause-specific models fine-tuned on proprietary precedent libraries and reduced manual review load for standard contracts by roughly one-third, improving reviewer precision on non-standard terms.
- Regulated analytics: A European asset manager used domain-tuned models in a controlled enclave to produce audit-ready investment summaries, simplifying compliance reporting under pan-European rules and internal audit requirements.
Evidence from benchmarks and studies
Community and industry benchmarks reflect the practical trade-offs. MLCommons' MLPerf Inference tracks latency and throughput across architectures; its 2025–26 cycles showed smaller encoder-decoder and decoder-only models delivering substantially higher throughput per dollar on routine NLP tasks. Separately, AI Workplace Tools’ August 2026 survey found that among respondents who adopted model portfolios, the median reported reduction in monthly inference spend was 37% (self-reported).
New risks and persistent challenges
The portfolio approach reduces some risks but adds others:
- Model sprawl and drift: Organizations now regularly manage dozens of active model artifacts. Our survey respondents reported an average of 14 deployed models per production domain, increasing the need for continuous evaluation pipelines.
- Consistency and orchestration: Routing decisions, fallback logic and harmonizing outputs between models demand stronger policy engines and human-in-loop validation for high-risk paths.
- Supply-chain and licensing complexity: Mixing open-source and commercial models increases legal and data-usage review workloads; procurement teams now require clear license and IP clauses.
Updated recommendations for CIOs and AI leaders (August 2026)
- Classify use-cases by business impact and regulatory risk: Maintain a risk matrix that maps each LLM use to a compliance category (e.g., low-risk routing vs. high-risk decisioning).
- Build a model catalog that is auditable: Record model provenance, training-data constraints, benchmark results, drift metrics and permitted deployment contexts. Tie entries to contractual metadata and SLA clauses.
- Adopt policy-driven inference gateways: Implement routing policies that select models based on cost, latency and risk tolerance — e.g., default to task models for routine intents, escalate to larger models with human review where uncertainty exceeds thresholds.
- Operationalize continuous evaluation: Deploy synthetic testing, adversarial probes and production-ground-truth sampling to detect drift across many small models. Set automated rollback criteria and shadowing tests for new model versions.
- Treat compute and data as audit scopes: Use confidential compute and signed attestations where regulations demand provenance. Include compute metering in cost and compliance reporting to finance and audit teams.
Impact: who benefits and who pays
Operational teams and compliance functions benefit from predictability and auditable behavior. Product managers win faster iteration via smaller models. But there is an upfront engineering tax: SRE and MLOps teams bear the integration burden, and procurement/legal must manage more complex licensing. Organizations that invest in robust selection, governance and automation tools will capture the greatest operational savings.
Reactions from the field
Not all respondents saw the same urgency. Anonymized comments from our survey illustrate the range: “Purpose-built models unlocked predictable budgets for our contact center,” said a head of AI at a U.S. insurer. “But maintaining 18 model variants across 6 services stretched our validation teams,” added a CTO at a European fintech.
What to watch next
- Regulatory updates: implementation details under the EU AI Act and guidance from U.S. agencies will clarify audit and documentation expectations through 2026–2027.
- Standardized benchmarks: expect more task-specific, audit-focused benchmarks from MLCommons and industry consortia that make model comparisons meaningful across compliance attributes.
- Runtime primitives: wider adoption of confidential compute, attestation, and standardized metering APIs will simplify hybrid deployments and audit trails.
FAQ: What enterprise leaders ask now
How much cost savings can we realistically expect from switching to smaller task models?
Savings vary by workload. In our August 2026 survey of 138 enterprise AI leads, the median reported monthly inference-cost reduction after adopting model portfolios was 37% (self-reported). Case studies range from modest single-digit savings to 3–5x reductions for very high-volume, low-risk routing tasks when moving from 70B+ models to optimized 3–12B models.
Do purpose-built models reduce regulatory risk under the EU AI Act and similar rules?
Purpose-built models can simplify compliance because they are easier to document, restrict in deployment, and run within controlled environments. However, the model itself is only one element — data provenance, human oversight, logging and impact assessments remain essential to meet regulatory requirements.
Should we prefer open-source or managed commercial domain models?
There is no one-size-fits-all answer. Open-source models give control and auditability but increase operational burden (hosting, patching, attestation). Managed services reduce operational load but can complicate data residency and provenance; many enterprises now use hybrid approaches—self-hosting for high-risk workloads and managed services for less sensitive functions.
How do we avoid model sprawl while maintaining specialization?
Govern the portfolio through a central model catalog, enforce lifecycle policies (deprecation, evaluation thresholds), and adopt feature flags and shadowing for gradual rollout. Invest in automation for continuous evaluation and drift detection so each model’s lifecycle is visible and actionable.